Galaxy Morphology Classification with the Sloan Digital Sky Survey#
Overview#
Galaxy morphology, the shape and structure of a galaxy, is one of the most fundamental observables in extragalactic astronomy [3]. The Hubble sequence classifies galaxies as ellipticals (smooth, dominated by old stellar populations, little ongoing star formation), lenticulars, spirals (a disk with spiral arms, ongoing star formation), and irregulars (no regular structure, often gas-rich, and sometimes disturbed by interactions). Understanding how morphology connects to physical properties such as colour, luminosity and stellar mass is central to galaxy evolution: how galaxies form, grow, and stop forming stars (“quench”) over cosmic time.
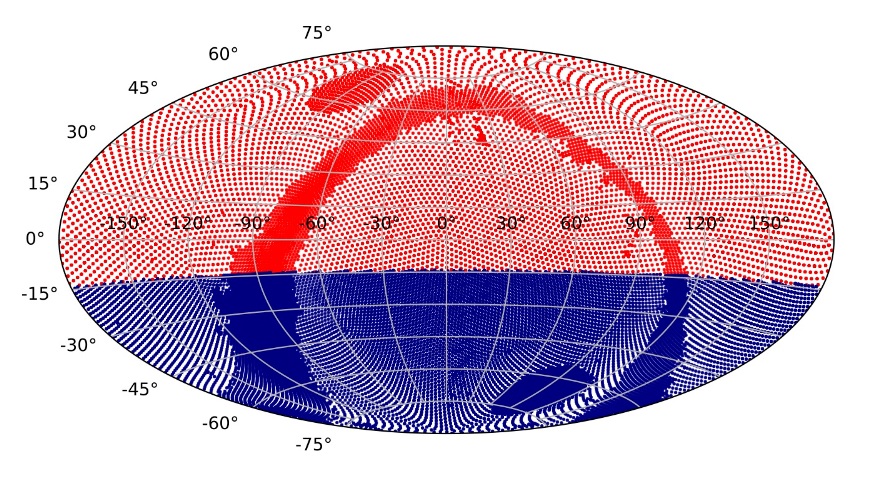
Modern surveys such as the Sloan Digital Sky Survey (SDSS) [1] observe far more galaxies than can be classified by eye. The Galaxy Zoo project solved this with citizen science [2], and machine learning can do it automatically and on even larger scales. In this project you will:
retrieve photometric and spectroscopic measurements of SDSS galaxies, together with their Galaxy Zoo morphological classifications;
train classical supervised classifiers to predict morphology from a few physical features;
build an artificial neural network (ANN) classifier and compare it with the classical ones; and
use Bayesian inference with MCMC to fit the red sequence of elliptical galaxies, and quantify the uncertainties of its parameters.
Data#
We query SDSS Data Release 17 [1] directly from the SkyServer web service (https://skyserver.sdss.org/dr17), which does not require an account. Larger queries can be run in CasJobs (https://skyserver.sdss.org/casjobs/), which requires a free account. The query joins three tables:
PhotoObj: photometry.modelMag_u…modelMag_zare magnitudes in the five SDSS bands;petroR50_randpetroR90_rare the radii (in arcsec) containing 50% and 90% of the r-band Petrosian flux;petroMag_ris the Petrosian r magnitude;fracDeV_ris the fraction of the light best fit by a de Vaucouleurs (elliptical-like) profile.SpecObj: spectroscopy, giving the redshiftzand the stellar velocity dispersionvelDisp(km/s).zooSpec: Galaxy Zoo 1 morphological classifications [2] for galaxies in the SDSS spectroscopic sample.spiralandellipticalflag galaxies whose (debiased) vote fraction for that class exceeds 80%; all other galaxies are flaggeduncertain.
We select galaxies (type = 3) with reliable redshifts between 0.01 and 0.25, and r-band magnitudes 14 < r < 17.77 (the limit of the SDSS main galaxy sample).
Setup#
%pip install --quiet emcee corner
import io
import os
import urllib.parse
import urllib.request

import numpy as np
import pandas as pd
import matplotlib.pyplot as plt
import seaborn as sns
import emcee, corner
import torch
import torch.nn as nn

from sklearn.model_selection import train_test_split, cross_val_score
from sklearn.preprocessing import StandardScaler
from sklearn.linear_model import LogisticRegression
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import classification_report, confusion_matrix, ConfusionMatrixDisplay, roc_auc_score

sns.set_theme(style='whitegrid')
SEED = 42
np.random.seed(SEED); torch.manual_seed(SEED)
SQL = """
SELECT TOP 20000
  p.objid, p.modelMag_u, p.modelMag_g, p.modelMag_r, p.modelMag_i, p.modelMag_z,
  p.modelMagErr_u, p.modelMagErr_r,
  p.petroR50_r, p.petroR90_r, p.petroMag_r, p.fracDeV_r,
  s.z AS redshift, s.velDisp,
  g.spiral, g.elliptical, g.uncertain
FROM PhotoObj AS p
JOIN SpecObj AS s ON s.bestobjid = p.objid
JOIN zooSpec AS g ON g.objid = p.objid
WHERE s.z BETWEEN 0.01 AND 0.25 AND s.zWarning = 0
  AND p.petroMag_r BETWEEN 14 AND 17.77 AND p.type = 3
"""

DATA_FILE = "sdss_galaxyzoo.csv"
if not os.path.exists(DATA_FILE):
    url = ("https://skyserver.sdss.org/dr17/SkyServerWS/SearchTools/SqlSearch?"
           + urllib.parse.urlencode({"cmd": SQL, "format": "csv"}))
    text = urllib.request.urlopen(url, timeout=600).read().decode()
    lines = text.splitlines()
    header = next(i for i, line in enumerate(lines) if line.startswith("objid"))   # skip the "#Table1" line
    pd.read_csv(io.StringIO("\n".join(lines[header:]))).to_csv(DATA_FILE, index=False)

df_raw = pd.read_csv(DATA_FILE)
print(df_raw.shape)
df_raw.head()
Questions#
Question 01#
What is the Hubble sequence? Describe the main morphological classes (elliptical, lenticular, spiral, irregular), and the physical properties that distinguish them, such as stellar age, gas content and star-formation rate. What does the colour–magnitude diagram of galaxies look like, and which physical processes drive its bimodality into a “red sequence” and a “blue cloud”? Ref. [3] is a good starting point.
Answer by creating and populating cells below (markdown and/or code):
Cleaning the data and feature engineering#
SDSS uses the value −9999 to flag missing measurements, and the velocity dispersion is set to 0 when it could not be measured. We remove such entries, label each galaxy using its Galaxy Zoo classification, and compute physically motivated features:
colours \(u - r\) and \(g - r\);
the concentration index \(C = R_{90}/R_{50}\), which is larger for centrally concentrated (elliptical-like) light profiles;
the half-light radius
petroR50_r;the absolute magnitude \(M_r = m_r - 5\log_{10}(d_L/\mathrm{Mpc}) - 25\), where the distance is approximated with Hubble’s law, \(d \approx cz/H_0\), with \(H_0 = 70\) km/s/Mpc;
the stellar velocity dispersion
velDisp.
df_raw = df_raw[(df_raw[['modelMag_u', 'modelMag_g', 'modelMag_r', 'modelMagErr_u']] > -1000).all(axis=1)]
df_raw = df_raw[df_raw['velDisp'] > 0].copy()

# Galaxy Zoo labels: keep galaxies with a confident ("clean") classification
df_raw['morphology'] = np.where(df_raw['elliptical'] == 1, 'elliptical',
                        np.where(df_raw['spiral'] == 1, 'spiral', 'uncertain'))
print(df_raw['morphology'].value_counts())

df_raw['color_ur']      = df_raw['modelMag_u'] - df_raw['modelMag_r']
df_raw['color_gr']      = df_raw['modelMag_g'] - df_raw['modelMag_r']
df_raw['concentration'] = df_raw['petroR90_r'] / df_raw['petroR50_r']
df_raw['abs_mag_r']     = df_raw['petroMag_r'] - 5 * np.log10(df_raw['redshift'] * 3e5 / 70) - 25
df_raw['color_ur_err']  = np.hypot(df_raw['modelMagErr_u'], df_raw['modelMagErr_r'])

FEATURES = ['color_ur', 'color_gr', 'concentration', 'petroR50_r', 'abs_mag_r', 'velDisp']
df = df_raw[df_raw['morphology'] != 'uncertain'][FEATURES + ['morphology', 'fracDeV_r', 'color_ur_err']].dropna()
df = df[df['concentration'].between(1, 5) & df['color_ur'].between(-1, 6)]
print(f"Final clean dataset: {len(df)} galaxies")
print(df['morphology'].value_counts())
Question 02#
Plot the distribution of each feature separately for elliptical and spiral galaxies (e.g. overlaid, normalized histograms), and a scatter plot of \(u - r\) versus \(M_r\) (the colour–magnitude diagram) coloured by class.
For each feature, should elliptical or spiral galaxies have higher values on average? Why? Do the plots confirm your expectations? Which single feature looks most discriminating?
Note that the sample contains roughly three times as many spirals as ellipticals. What accuracy would a trivial classifier that always predicts “spiral” achieve?
Answer by creating and populating cells below (markdown and/or code):
Supervised Classification#
X = df[FEATURES].values
y = (df['morphology'] == 'elliptical').astype(int).values

X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=SEED, stratify=y)
scaler     = StandardScaler()
X_train_sc = scaler.fit_transform(X_train)
X_test_sc  = scaler.transform(X_test)

lr = LogisticRegression(max_iter=500, random_state=SEED)
lr.fit(X_train_sc, y_train)
print(f"Logistic Regression 5-fold CV accuracy: {cross_val_score(lr, X_train_sc, y_train, cv=5).mean():.4f}")

rf = RandomForestClassifier(n_estimators=200, max_depth=10, random_state=SEED, n_jobs=-1)
rf.fit(X_train_sc, y_train)
print(f"Random Forest       5-fold CV accuracy: {cross_val_score(rf, X_train_sc, y_train, cv=5).mean():.4f}")
fig, axes = plt.subplots(1, 2, figsize=(11, 4))
for ax, model, name in zip(axes, [lr, rf], ['Logistic Regression', 'Random Forest']):
    ConfusionMatrixDisplay(confusion_matrix(y_test, model.predict(X_test_sc)),
                           display_labels=['Spiral', 'Elliptical']).plot(ax=ax, colorbar=False, cmap='Blues')
    ax.set_title(name)
plt.tight_layout(); plt.show()
Question 03#
Let’s compare the two baseline classifiers.
a) Print the classification_report for each model on the test set, and compare the precision, recall and F1-score of each class. Which model performs better overall? With imbalanced classes, why is accuracy alone not a sufficient metric? Also compute the ROC AUC of each model.
b) Plot the random forest’s feature importances. Which features are the most discriminating? Does this match your prediction from Question 02?
c) Why is 5-fold cross-validation preferable to evaluating the accuracy on a single test split?
d) Labels matter. An alternative, purely photometric way to label galaxies is the light-profile parameter fracDeV_r (e.g. “smooth” if fracDeV_r > 0.7, “featured” if < 0.3). How often does this label agree with the Galaxy Zoo classification? What fraction of Galaxy Zoo spirals would be called “smooth”? Retrain the random forest with the fracDeV_r labels: is the accuracy higher or lower? Why might a classifier look better on such labels while being worse at predicting what humans see? (Hint: how is the concentration feature related to the light profile?)
Answer by creating and populating cells below (markdown and/or code):
Artificial Neural Network Classifier#
Now we train a fully connected neural network in PyTorch, as in the Artificial Neural Networks and Deep Learning lectures. We hold out part of the training set for validation, and use early stopping: we keep the weights from the epoch with the lowest validation loss.
X_tr, X_val, y_tr, y_val = train_test_split(X_train_sc, y_train, test_size=0.15, random_state=SEED, stratify=y_train)
to_t = lambda a: torch.tensor(a, dtype=torch.float32)
X_tr_t, X_val_t, X_test_t = to_t(X_tr), to_t(X_val), to_t(X_test_sc)
y_tr_t, y_val_t = to_t(y_tr).unsqueeze(1), to_t(y_val).unsqueeze(1)

ann = nn.Sequential(
    nn.Linear(X_tr.shape[1], 128), nn.ReLU(), nn.BatchNorm1d(128), nn.Dropout(0.3),
    nn.Linear(128, 64), nn.ReLU(), nn.Dropout(0.3),
    nn.Linear(64, 1)                       # logit; the sigmoid is inside the loss
)
loss_fn = nn.BCEWithLogitsLoss()
opt = torch.optim.Adam(ann.parameters(), lr=1e-3)
print(ann, "\ntrainable parameters:", sum(p.numel() for p in ann.parameters()))
history = {"loss": [], "val_loss": [], "acc": [], "val_acc": []}
best_val, best_state, patience, wait = np.inf, None, 10, 0
for epoch in range(200):
    ann.train()
    perm = torch.randperm(len(X_tr_t))
    for b in range(0, len(perm), 64):
        i = perm[b:b + 64]
        loss = loss_fn(ann(X_tr_t[i]), y_tr_t[i])
        opt.zero_grad(); loss.backward(); opt.step()
    ann.eval()
    with torch.no_grad():
        out_tr, out_val = ann(X_tr_t), ann(X_val_t)
        history["loss"].append(loss_fn(out_tr, y_tr_t).item()); history["val_loss"].append(loss_fn(out_val, y_val_t).item())
        history["acc"].append(((out_tr > 0) == (y_tr_t > 0.5)).float().mean().item())
        history["val_acc"].append(((out_val > 0) == (y_val_t > 0.5)).float().mean().item())
    if history["val_loss"][-1] < best_val:
        best_val, wait = history["val_loss"][-1], 0
        best_state = {k: v.clone() for k, v in ann.state_dict().items()}
    else:
        wait += 1
        if wait >= patience:
            break
ann.load_state_dict(best_state)       # early stopping: restore the best weights
print("stopped after", epoch + 1, "epochs")

fig, axes = plt.subplots(1, 2, figsize=(12, 4))
for ax, key, title in zip(axes, ['loss', 'acc'], ['Loss', 'Accuracy']):
    ax.plot(history[key], label='Train'); ax.plot(history[f'val_{key}'], label='Validation')
    ax.set_title(title); ax.set_xlabel('Epoch'); ax.legend()
plt.tight_layout(); plt.show()

ann.eval()
with torch.no_grad():
    y_prob = torch.sigmoid(ann(X_test_t)).numpy().ravel()
y_pred = (y_prob >= 0.5).astype(int)
print(classification_report(y_test, y_pred, target_names=['Spiral', 'Elliptical']))
print("ROC AUC: %.4f" % roc_auc_score(y_test, y_prob))
Question 04#
Let’s analyze the ANN classifier.
a) How does the ANN’s test performance compare with the two baseline classifiers of Question 03? With only six input features, would you expect a neural network to have a large advantage? Why or why not?
b) Look at the loss and accuracy curves. Is there overfitting? How does early stopping help, and why do we restore the weights of the best epoch?
c) Make a histogram of the ANN output probability y_prob, coloured by the true class. Are many galaxies near the decision boundary, \(P \approx 0.5\)? What might these galaxies physically be? (Think of lenticulars, edge-on spirals, and spirals with large bulges.)
Answer by creating and populating cells below (markdown and/or code):
Bayesian Inference: The Galaxy Red Sequence#
Elliptical galaxies follow a tight red sequence: more luminous ellipticals are systematically redder. We model this as a linear relation with intrinsic scatter:
Here \(\sigma_{\mathrm{obs},i}\) is the measurement uncertainty of each galaxy’s colour, computed from the SDSS magnitude errors. We use emcee [4] to sample the posterior distribution of \((\alpha, \beta, \ln\sigma_\mathrm{int})\), with uniform priors.
rs  = df[(df['morphology'] == 'elliptical') & df['color_ur'].between(1.5, 4.0)]
idx = np.random.default_rng(SEED).choice(len(rs), size=min(800, len(rs)), replace=False)
xd, yd, sig = rs['abs_mag_r'].values[idx], rs['color_ur'].values[idx], rs['color_ur_err'].values[idx]

def log_likelihood(theta, x, y, se):
    a, b, lsig = theta
    s = np.sqrt(np.exp(lsig)**2 + se**2)
    return -0.5 * np.sum(((y - (a + b*x)) / s)**2 + np.log(2*np.pi*s**2))

def log_prior(theta):
    a, b, lsig = theta
    return 0.0 if (-10 < a < 15 and -2 < b < 2 and -5 < lsig < 2) else -np.inf

def log_post(theta, x, y, se):
    lp = log_prior(theta)
    return lp + log_likelihood(theta, x, y, se) if np.isfinite(lp) else -np.inf

b0, a0 = np.polyfit(xd, yd, 1)
pos = np.array([a0, b0, np.log(0.1)]) + 1e-3 * np.random.randn(32, 3)
sampler = emcee.EnsembleSampler(32, 3, log_post, args=(xd, yd, sig))
sampler.run_mcmc(pos, 2000, progress=True)
print("mean acceptance fraction: %.2f" % np.mean(sampler.acceptance_fraction))
flat = sampler.get_chain(discard=300, thin=10, flat=True)
a_med, b_med, lsig_med = np.median(flat, axis=0)
print(f"alpha     = {a_med:.3f} +/- {flat[:,0].std():.3f}")
print(f"beta      = {b_med:.3f} +/- {flat[:,1].std():.3f}")
print(f"sigma_int = {np.exp(lsig_med):.3f} +/- {np.exp(flat[:,2]).std():.3f} mag")

sp = flat.copy(); sp[:, 2] = np.exp(sp[:, 2])
corner.corner(sp, labels=[r'$\alpha$', r'$\beta$', r'$\sigma_{\rm int}$'],
              quantiles=[0.16, 0.5, 0.84], show_titles=True, color='steelblue')
plt.suptitle('Posterior: red-sequence parameters', y=1.01); plt.show()

xr = np.linspace(xd.min(), xd.max(), 100)
draws = flat[np.random.choice(len(flat), 200)]
pred = draws[:, 0:1] + draws[:, 1:2] * xr          # same posterior draw for alpha and beta

plt.figure(figsize=(8, 5))
plt.scatter(xd, yd, s=5, alpha=0.3, color='#e63946', label='Elliptical galaxies')
plt.fill_between(xr, np.percentile(pred, 16, 0), np.percentile(pred, 84, 0), alpha=0.4, color='navy', label=r'$1\sigma$ posterior')
plt.plot(xr, a_med + b_med*xr, color='navy', lw=2, label='Median fit')
plt.xlabel(r'$M_r$'); plt.ylabel('u − r'); plt.gca().invert_xaxis()
plt.title('Bayesian fit: red sequence'); plt.legend(); plt.tight_layout(); plt.show()
Question 05#
Let’s interpret the Bayesian MCMC results.
a) What is the sign of the slope \(\beta\), and what does it mean physically, given that brighter galaxies have more negative \(M_r\)? What does the fact that more massive ellipticals are redder imply about their stellar populations (age, metallicity)?
b) Are \(\alpha\) and \(\beta\) correlated in the corner plot? Why does a slope–intercept degeneracy arise in a linear fit, and how could you reduce it (hint: centre the \(x\) values)?
c) Check that the MCMC has converged, e.g. by plotting the chains and estimating the autocorrelation time (sampler.get_autocorr_time()). Are 2000 steps enough?
d) The intrinsic scatter \(\sigma_\mathrm{int}\) captures real physical diversity among ellipticals beyond measurement noise. Compare it with the typical measurement error \(\sigma_\mathrm{obs}\). What astrophysical processes could contribute to scatter in the red sequence?
Answer by creating and populating cells below (markdown and/or code):
Question 06#
a) Compare the three classifiers and comment on their performance and on what limits it.
b) Bayesian vs. point estimates: What does MCMC add that a simple least-squares fit cannot? Why does quantifying \(\sigma_\mathrm{int}\) and the full parameter uncertainties matter scientifically?
c) Discuss the limitations of this project and possible extensions. For example, consider the Hubble-law distances and the lack of K-corrections and dust-extinction corrections in \(M_r\) and the colours; the use of only confidently classified galaxies; and using the galaxy images with a convolutional neural network (see the Galaxy Zoo project).
Answer by creating and populating cells below (markdown and/or code):
References#
[1] Abdurro’uf et al. (SDSS Collaboration), “The Seventeenth Data Release of the Sloan Digital Sky Surveys,” Astrophys. J. Suppl. 259, 35 (2022). doi:10.3847/1538-4365/ac4414, arXiv:2112.02026
[2] C. Lintott et al., “Galaxy Zoo 1: data release of morphological classifications for nearly 900,000 galaxies,” Mon. Not. R. Astron. Soc. 410, 166 (2011). doi:10.1111/j.1365-2966.2010.17432.x, arXiv:1007.3265
[3] C. J. Conselice, “The Evolution of Galaxy Structure Over Cosmic Time,” Annu. Rev. Astron. Astrophys. 52, 291 (2014). doi:10.1146/annurev-astro-081913-040037, arXiv:1403.2783
[4] D. Foreman-Mackey, D. W. Hogg, D. Lang, J. Goodman, “emcee: The MCMC Hammer,” Publ. Astron. Soc. Pac. 125, 306 (2013). doi:10.1086/670067, arXiv:1202.3665
[5] SDSS SkyServer (DR17): https://skyserver.sdss.org/dr17; CasJobs: https://skyserver.sdss.org/casjobs/
Acknowledgements#
Initial version: Ashi Poorey with some guidance from Mark Neubauer
Revised: 2026
SDSS DR17 data from the SkyServer; morphological classifications from Galaxy Zoo 1.
© Copyright 2026