Searching for Exotic Particles#
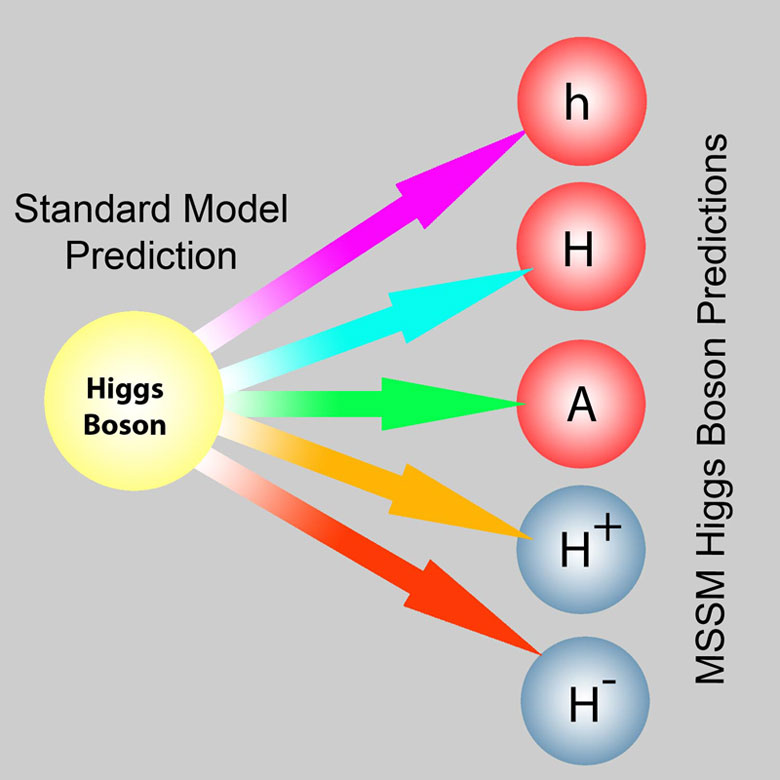
The SM predicts a single Higgs boson. Supersymmetric extensions such as the Minimal Supersymmetric Standard Model (MSSM) predict five: the light neutral \(h\), a heavy neutral \(H\), a pseudoscalar \(A\), and two charged bosons \(H^\pm\).
Learning Objectives#
By the end of this project you should be able to:
explain why physicists expect new particles beyond the Standard Model (SM) and how they would be searched for at the LHC;
describe the hypothetical signal processes and the SM backgrounds in two benchmark datasets;
load and inspect very large tabular physics datasets efficiently, and spot problems in file formats;
connect each feature to a physical quantity reconstructed in a collider detector; and
use histograms to judge which features separate signal from background, and how this depends on the unknown mass of the new particle. This is the starting point for the classifiers in Project 02.
Overview#
The SM of particle physics is extraordinarily successful, but it leaves important questions open. It contains no dark-matter candidate, it does not explain the matter–antimatter asymmetry of the universe, and it does not explain why the Higgs boson mass is so much lighter than the Planck scale. Many proposed extensions of the SM, including supersymmetry and models with extended Higgs sectors or new heavy gauge bosons, predict exotic particles that have not yet been discovered. Several of these theories also link elementary particle physics to cosmology and the very early universe. If such particles exist, some could contribute significantly to the dark matter in the universe or resolve other puzzles in particle physics.
In July 2012 the ATLAS and CMS collaborations at CERN’s Large Hadron Collider (LHC) announced the discovery of a new particle with a mass near 125 GeV, consistent with the Higgs boson predicted by the Standard Model (SM). Neubauer’s research group at Illinois contributed to the data analysis in the ATLAS discovery paper. François Englert and Peter Higgs received the 2013 Nobel Prize in Physics for the theoretical prediction. [3], [4], [5] Whether the 125 GeV boson is the only Higgs boson is still an open question. Searching for additional Higgs bosons and other new heavy particles is a central goal of the LHC programme.
Exotic signals are rare and sit under large backgrounds from SM processes that produce the same detector signature. Physicists use machine learning, trained on Monte Carlo simulations, to separate them. In this project you will explore two public benchmark datasets built for this purpose:
HEPMASS [2]: a hypothetical heavy particle \(X\) of unknown mass decaying to a top-quark pair, \(X\to t\bar t\), against the SM background of \(t\bar t\) production.
HIGGS [1]: a heavy neutral Higgs boson \(H^0\) decaying through a charged Higgs boson \(H^\pm\) to \(W^\mp W^\pm b\bar b\), against the SM \(t\bar t\) background.
Data Sources#
HEPMASS dataset (UCI Machine Learning Repository, D. Whiteson, 2016) [6]
Dataset page: https://archive.ics.uci.edu/dataset/347/hepmass
Course mirror (please use these). Each training file has 7 million events (about 1.7 GB compressed) and each test file 3.5 million (about 0.9 GB):
The mass of the new particle is unknown, so there are three versions of the dataset. Each is 50% signal and 50% background, split into a training set of 7 million events and a test set of 3.5 million.
1000: the signal particle has \(m_X = 1000\) GeV. There is no mass feature, since all signal events have the same mass.not1000: \(m_X\) is drawn uniformly from {500, 750, 1250, 1500} GeV. The mass is included as an extra input feature; background events are assigned a mass chosen at random from the same set.all: \(m_X\) is drawn uniformly from {500, 750, 1000, 1250, 1500} GeV, with the mass feature handled as fornot1000.
The first column is the class label (1 = signal, 0 = background). It is followed by 27 normalized features (22 low-level, then 5 high-level) and, for not1000 and all, a 28th column holding the mass. The dataset authors preprocessed several features by taking \(\log(x + 10^{-5})\) and then rescaling. See the readme for details.
⚠️ File-format trap: each file starts with a header line beginning with #. In the 1000_* files this header lists only 27 names (# label, f0 … f25), but every data row has 28 values. A plain pd.read_csv("1000_train.csv.gz") therefore silently makes the label the DataFrame index and shifts every column name by one. Skip the header and supply your own column names, as in the cell below.
HIGGS dataset (UCI Machine Learning Repository, D. Whiteson, 2014) [7]
Dataset page: https://archive.ics.uci.edu/dataset/280/higgs
Course mirror (please use this; 11 million events, about 2.8 GB compressed): https://courses.physics.illinois.edu/phys498mlp/sp2025/data/projects/HiggsTauTau/HIGGS.csv.gz
There is no header row. Column 1 is the label, followed by 21 low-level and 7 high-level features (described in Question 10). The dataset authors use the last 500,000 rows as the test set.
Practical tips
The full files are large. The cell below streams and decompresses only the first
N_EVENTSrows of each file over the network, which takes seconds. Plainpd.read_csv(<URL>, nrows=...)downloads the whole file before applyingnrows.A few hundred thousand events per dataset are plenty for this project.
import gzip
import urllib.request

import numpy as np
import pandas as pd
import matplotlib.pyplot as plt

N_EVENTS = 300_000  # per file; increase once your code works

def read_events(url, nrows, skip_header=False):
    """Stream the first `nrows` events of a gzipped CSV without downloading all of it."""
    with urllib.request.urlopen(url) as response, gzip.GzipFile(fileobj=response) as f:
        if skip_header:
            f.readline()
        return pd.read_csv(f, header=None, nrows=nrows)

# --- HEPMASS ---
HEPMASS_URL = "https://courses.physics.illinois.edu/phys498mlp/sp2025/data/projects/ExoticParticles/hepmass/"
hepmass_features = [f"f{i}" for i in range(27)]

hep1000 = read_events(HEPMASS_URL + "1000_train.csv.gz", N_EVENTS, skip_header=True)
hep1000.columns = ["label"] + hepmass_features

hepnot1000 = read_events(HEPMASS_URL + "not1000_train.csv.gz", N_EVENTS, skip_header=True)
hepnot1000.columns = ["label"] + hepmass_features + ["mass"]

# --- HIGGS ---
HIGGS_URL = "https://courses.physics.illinois.edu/phys498mlp/sp2025/data/projects/HiggsTauTau/HIGGS.csv.gz"
higgs_low = (["lepton_pT", "lepton_eta", "lepton_phi",
              "missing_energy_magnitude", "missing_energy_phi"]
             + [f"jet{i}_{v}" for i in range(1, 5) for v in ("pt", "eta", "phi", "btag")])
higgs_high = ["m_jj", "m_jjj", "m_lv", "m_jlv", "m_bb", "m_wbb", "m_wwbb"]

higgs = read_events(HIGGS_URL, N_EVENTS)
higgs.columns = ["label"] + higgs_low + higgs_high

hep1000.head()
Questions#
Answer each question in a markdown cell directly below it (add code cells where needed). For the background questions in Part A, aim for one to two well-organized paragraphs, and cite your sources. The references at the end of this notebook are a good starting point. Your notebook should run from top to bottom without errors.
Part A: Physics background#
Question 01#
What is the Large Hadron Collider (LHC)? What about the LHC makes it possible to produce heavy particles like the Higgs boson? Include the relevant quantitative parameters, such as the proton–proton center-of-mass energy \(\sqrt{s}\) and the luminosity, and explain why each one matters for producing a rare, heavy particle.
Question 02#
The Higgs boson was the last particle predicted by the Standard Model (SM) to be discovered. In what ways does it play a particularly important role in the SM? Consider, for example, how the \(W\) and \(Z\) bosons and the fermions acquire mass.
What open questions does the SM leave unanswered that motivate searches for new particles?
Question 03#
Briefly describe the ATLAS and CMS experiments that record LHC proton–proton collision data. What are the main detector subsystems, and which particles does each one measure? Relate your answer to the objects that appear in the datasets below: electrons and muons, jets, \(b\)-tagged jets, and missing transverse momentum.
Question 04#
Based on Ref. [1], describe the exotic particles in the two benchmark models (a) HIGGS and (b) SUSY. Why would discovering them be important for fundamental physics? For each model, write the signal process as a chain of decays and name the SM background process that mimics it.
Part B: The HEPMASS dataset#
Questions 05 to 09 use the HEPMASS dataset. Use the 1000_train and not1000_train files.
Question 05#
What are the size and shape of each of the three HEPMASS datasets (training and test)? Check the signal fraction and the set of mass values that appear in each. Inspect the raw header line of each file. What problem do you find in the 1000 files, and what would happen if you read them with a default pd.read_csv call?
Question 06#
Read Ref. [2] and the dataset readme, then answer:
What are the signal (\(X\to t\bar t\)) and background (\(t\bar t\)) processes? Write each as a chain of decays down to the final-state objects in the semi-leptonic channel.
What physical quantity does each of the 27 features represent: the lepton, the missing transverse momentum, the number of jets, and the jets’ \(p_T\), \(\eta\), \(\phi\) and \(b\)-tag values, plus the high-level masses \(m_{jj}\), \(m_{jjj}\), \(m_{\ell\nu}\), \(m_{j\ell\nu}\) and \(m_{WWbb}\)? A table is a good format.
The features have been preprocessed (log transform and rescaling). Why might the dataset authors have done this, and what does it mean for interpreting the histograms in physical units?
Question 07#
For the 1000 dataset, plot histograms of all 27 features with signal and background overlaid on the same axes, normalized to unit area with the same bin edges for both classes. Arrange the plots in a grid. Which features show the most significant differences between signal and background, and why? Explain physically, using your answer to Question 06.
Question 08#
Repeat Question 07 for the not1000 dataset. In addition, plot the distribution of the reconstructed resonance mass \(m_{WWbb}\) for signal separately for each value of the mass feature, overlaid with the background. Compare with Fig. 4 of Ref. [2].
Question 09#
What differences do you find between the not1000 and 1000 datasets? How does the separation between signal and background depend on \(m_X\)? Why are background events assigned a random value of the mass feature? What advantage does a classifier that takes the mass as an input (a “parameterized” classifier, Ref. [2]) have over training a separate classifier for each mass?
Part C: The HIGGS dataset#
Questions 10 and 11 use the HIGGS dataset.
Question 10#
What is the size and shape of the HIGGS dataset, and what fraction of its events are signal? The UCI description says the first 21 features (columns 2–22) are kinematic properties measured by the detector, and the last 7 are high-level features that physicists derived from the first 21 to help discriminate between the two classes. Using Ref. [1], explain what physical quantity each of the 28 features represents (\(p_T\), \(\eta\), \(\phi\), \(b\)-tag, missing energy, and the invariant masses \(m_{jj}\), \(m_{jjj}\), \(m_{\ell\nu}\), \(m_{j\ell\nu}\), \(m_{b\bar b}\), \(m_{Wb\bar b}\), \(m_{WWb\bar b}\)). For the high-level features, what would you expect each invariant-mass distribution to look like for signal compared with background, and why?
Question 11#
Plot histograms of all 28 HIGGS features with signal and background overlaid, normalized to unit area, in a grid (e.g., 7 × 4). Which features show the most significant differences between signal and background? Do the high-level features separate the classes better than the low-level ones? How do your conclusions compare with those for HEPMASS?
Optional extension: for both datasets, rank the features by a single number that measures separation, for example the area under the ROC curve obtained when each feature is used alone as a discriminant (sklearn.metrics.roc_auc_score), and compare the ranking with your visual impression.
References#
[1] P. Baldi, P. Sadowski, D. Whiteson, “Searching for exotic particles in high-energy physics with deep learning,” Nature Communications 5, 4308 (2014). doi:10.1038/ncomms5308, arXiv:1402.4735
[2] P. Baldi, K. Cranmer, T. Faucett, P. Sadowski, D. Whiteson, “Parameterized neural networks for high-energy physics,” Eur. Phys. J. C 76, 235 (2016). doi:10.1140/epjc/s10052-016-4099-4, arXiv:1601.07913
[3] ATLAS Collaboration, “Observation of a new particle in the search for the Standard Model Higgs boson with the ATLAS detector at the LHC,” Phys. Lett. B 716, 1 (2012). doi:10.1016/j.physletb.2012.08.020, arXiv:1207.7214
[4] CMS Collaboration, “Observation of a new boson at a mass of 125 GeV with the CMS experiment at the LHC,” Phys. Lett. B 716, 30 (2012). doi:10.1016/j.physletb.2012.08.021, arXiv:1207.7235
[5] The Nobel Prize in Physics 2013 (F. Englert and P. W. Higgs). https://www.nobelprize.org/prizes/physics/2013/summary/
[6] D. Whiteson, “HEPMASS” [Dataset], UCI Machine Learning Repository (2016). doi:10.24432/C5PP5W
[7] D. Whiteson, “HIGGS” [Dataset], UCI Machine Learning Repository (2014). doi:10.24432/C5V312
Acknowledgements#
Initial version: Mark Neubauer
Revised: 2026
© Copyright 2026