Modeling Fluid Flow Past a Cylinder#
Overview#
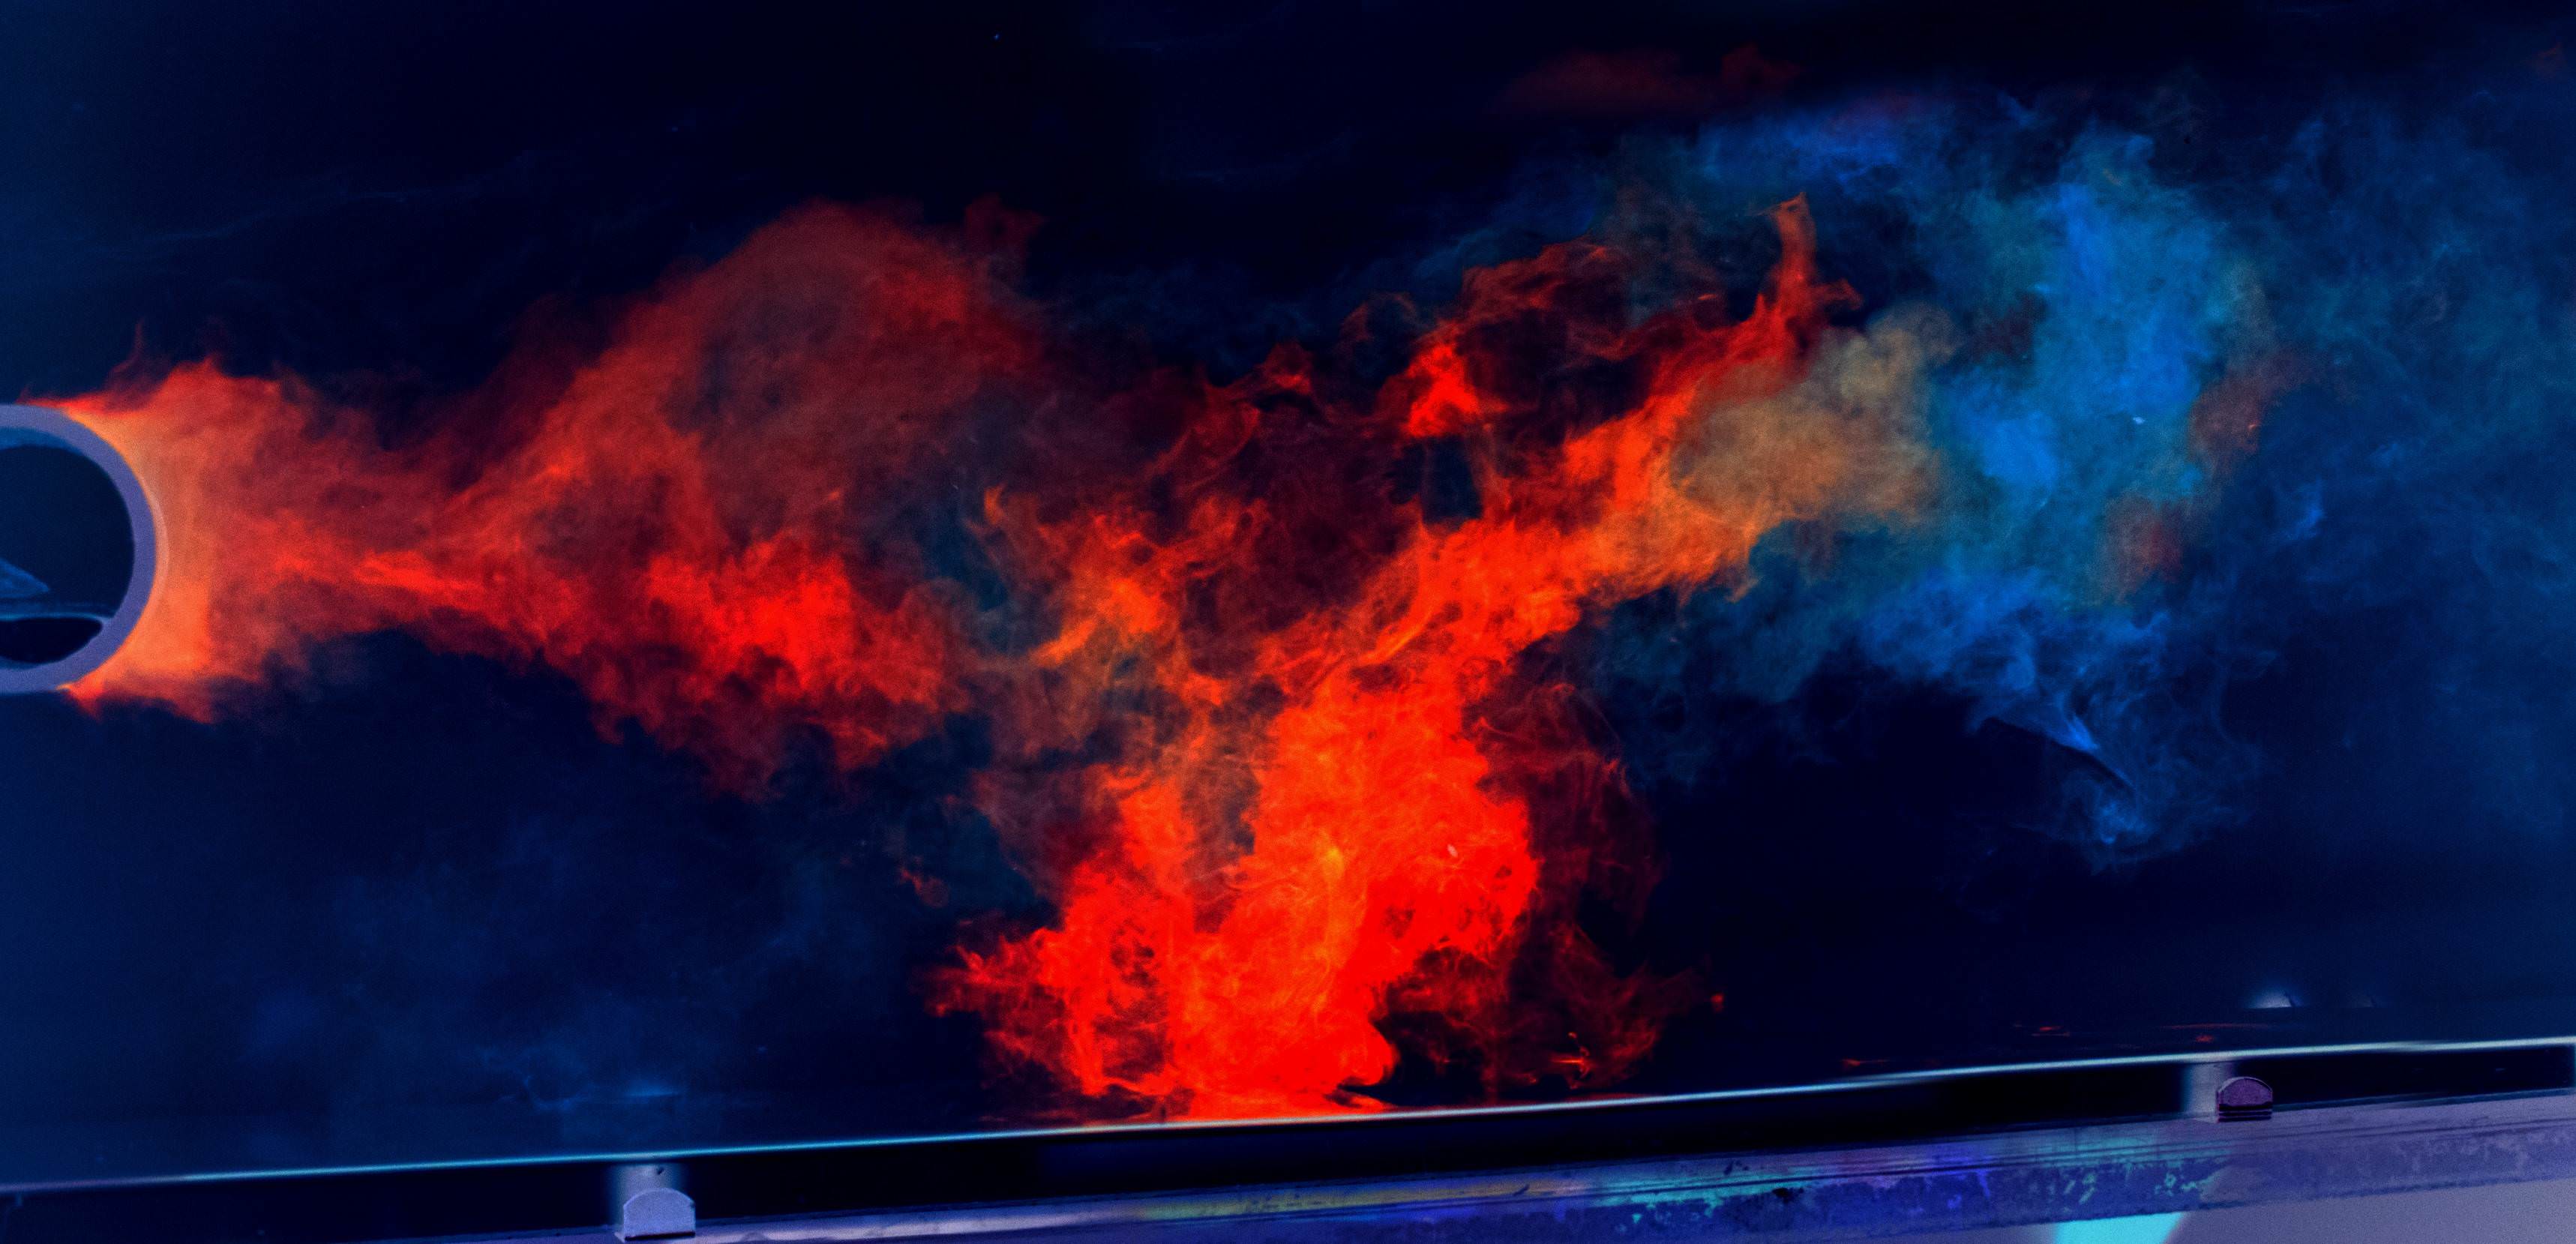
Fluid dynamics is central to many problems in engineering and physics, and modelling it is increasingly important. Many of these problems are very expensive to model numerically or experimentally: multiphase flows (e.g. the dispersion of pollutants or disease), hypersonics (e.g. spacecraft atmospheric re-entry), and fluid–structure interaction (e.g. bio-inspired motion).
This project applies physics-informed neural networks (PINNs) to a classic fluid-mechanics problem: the wake behind a cylinder. Embedding the governing equations into the training of a neural network is a promising way to deal with situations where data are scarce.
We start with an introduction to PINNs and a small worked example. Then we build a PINN for the cylinder wake, quantify its accuracy and uncertainty, and test how little data is needed to train a good PINN.
Learning Objectives#
Explain how a PINN combines data with a differential equation, and how automatic differentiation makes this possible.
Implement a PINN in PyTorch, first for a simple ODE and then for the 2D incompressible Navier–Stokes equations.
Evaluate a PINN’s accuracy, including for a quantity it is never trained on (the pressure), and estimate its uncertainty.
Investigate how the physics constraint compensates for limited training data.
Introduction to Physics-Informed Neural Networks#
A standard neural network learns a function only from data. Outside the region covered by the data it has no reason to behave sensibly, and it knows nothing about the physical laws the data obey. A physics-informed neural network [1], [2] represents the solution of a differential equation, \(u_\theta(\mathbf{x}, t)\), as a neural network with parameters \(\theta\), and trains it with a loss that has two parts:
The data loss compares the network with measured or simulated values at \(N_d\) points.
The physics loss is the residual of the governing equation \(\mathcal{N}[u] = 0\), e.g. \(\mathcal{N}[u] = u_t + u\,u_x - \nu\, u_{xx}\) for Burgers’ equation. It is evaluated at \(N_c\) collocation points, which can be placed anywhere in the domain and need no data.
The derivatives in \(\mathcal{N}[u_\theta]\) are computed exactly with automatic differentiation, the same machinery used for backpropagation. In PyTorch, this is
torch.autograd.grad(..., create_graph=True), which can be applied repeatedly for higher derivatives.
The same framework solves two kinds of problems:
forward problems, where the equation and its coefficients are known and we want the solution, possibly from few or no data; and
inverse problems, where unknown coefficients of the equation (e.g. a viscosity) are made trainable parameters and inferred from data.
PINNs are not magic. Training can be slow and hard to balance; plain networks struggle to represent fine-scale or high-frequency structure; and the result is only as good as the assumed physics. See the reviews [2], [3] for the current state of the field.
Automatic differentiation in PyTorch#
The cell below shows how to compute first and second derivatives of a network’s output with respect to its input. We check them on a function whose derivatives we know.
import numpy as np
import matplotlib.pyplot as plt
import torch
import torch.nn as nn

def grad(f, x):
    """df/dx for a batch, keeping the graph so that we can differentiate again (and backpropagate through it)."""
    return torch.autograd.grad(f, x, grad_outputs=torch.ones_like(f), create_graph=True)[0]

x = torch.linspace(0, 2 * np.pi, 5).reshape(-1, 1).requires_grad_(True)
f = torch.sin(x)
df, d2f = grad(f, x), grad(grad(f, x), x)
print("df/dx   - cos(x):", (df - torch.cos(x)).abs().max().item())
print("d2f/dx2 + sin(x):", (d2f + torch.sin(x)).abs().max().item())
A worked example: the damped harmonic oscillator#
Consider a damped oscillator, \(\ddot x + 2\delta\,\dot x + \omega_0^2\, x = 0\), with \(x(0) = 1\) and \(\dot x(0) = 0\). We use \(\delta = 2\) and \(\omega_0 = 20\) (underdamped). Suppose we have only 10 measurements, all in the first 40% of the time interval. We train two identical networks:
a plain neural network (NN) on the data alone, and
a PINN on the same data plus the residual of the equation at 40 collocation points spread over the whole interval.
Training both takes about 15 seconds on a laptop.
torch.manual_seed(123)
delta, w0 = 2.0, 20.0

def exact(t):
    w = np.sqrt(w0**2 - delta**2); phi = np.arctan(-delta / w); A = 1 / (2 * np.cos(phi))
    return np.exp(-delta * t) * 2 * A * np.cos(phi + w * t)

t_all = np.linspace(0, 1, 500).reshape(-1, 1)
x_all = exact(t_all)
t_data, x_data = t_all[0:200:20], x_all[0:200:20]          # 10 points in [0, 0.4)
t_d = torch.tensor(t_data, dtype=torch.float32)
x_d = torch.tensor(x_data, dtype=torch.float32)
t_c = torch.linspace(0, 1, 40).reshape(-1, 1).requires_grad_(True)   # collocation points

def make_net():
    return nn.Sequential(nn.Linear(1, 32), nn.Tanh(), nn.Linear(32, 32), nn.Tanh(),
                         nn.Linear(32, 32), nn.Tanh(), nn.Linear(32, 1))

predictions = {}
for kind in ["NN", "PINN"]:
    net = make_net()
    opt = torch.optim.Adam(net.parameters(), lr=1e-3)
    for it in range(15000):
        loss = ((net(t_d) - x_d) ** 2).mean()                       # data loss
        if kind == "PINN":
            x_c = net(t_c)
            dx = grad(x_c, t_c)
            residual = grad(dx, t_c) + 2 * delta * dx + w0**2 * x_c   # x'' + 2 delta x' + w0^2 x
            loss = loss + 1e-4 * (residual ** 2).mean()               # physics loss (weighted)
        opt.zero_grad(); loss.backward(); opt.step()
    with torch.no_grad():
        predictions[kind] = net(torch.tensor(t_all, dtype=torch.float32)).numpy()

fig, axes = plt.subplots(1, 2, figsize=(12, 3.5), sharey=True)
for ax, kind in zip(axes, ["NN", "PINN"]):
    ax.plot(t_all, x_all, "k-", lw=1, label="exact")
    ax.plot(t_all, predictions[kind], "r--", label=kind)
    ax.plot(t_data, x_data, "bo", label="training data")
    if kind == "PINN":
        ax.plot(t_c.detach(), np.zeros(len(t_c)), "g|", ms=10, label="collocation points")
    rmse = np.sqrt(np.mean((predictions[kind][200:] - x_all[200:]) ** 2))
    ax.set_title(f"{kind}: RMSE for t > 0.4 = {rmse:.3f}"); ax.set_xlabel("t"); ax.legend(fontsize=8)
plt.tight_layout(); plt.show()
Question 04: Understanding the PINN#
Using the example above:
Why does the plain network fail for \(t > 0.4\), while the PINN succeeds even though it has no data there?
The physics loss is multiplied by a weight \(10^{-4}\). Why is such a small weight needed here? (Hint: compare the size of \(\omega_0^2 x\) with the size of \(x\).) Try weights of \(10^{-2}\) and \(10^{-6}\). What happens?
Model misspecification: train the PINN with the wrong frequency, e.g. \(\omega_0 = 15\) in the residual (but the same data). What happens to the fit? What does this tell you about trusting a PINN’s physics?
(Optional) Inverse problem: make \(\omega_0\) a trainable parameter (
w = nn.Parameter(torch.tensor(10.0)), added to the optimizer), and use data over the whole interval. Does the PINN recover \(\omega_0 = 20\)?
[ Answer Here ]
Data Sources#
The data are the simulation of the 2D flow past a circular cylinder used in Ref. [1], from the authors’ public repository (MIT license):
maziarraissi/PINNs (24 MB)
The flow was computed with the spectral/hp-element solver Nektar++ [4], in nondimensional units: cylinder diameter \(D = 1\), free-stream velocity \(U_\infty = 1\), and Reynolds number \(Re = U_\infty D/\nu = 100\), i.e. kinematic viscosity \(\nu = 0.01\). At this Reynolds number the flow forms a periodic von Kármán vortex street. The file contains the velocity \((u, v)\) and pressure \(p\) in a rectangular region downstream of the cylinder:
5000 spatial points on a 100 × 50 grid, with \(x \in [1, 8]\) and \(y \in [-2, 2]\) (the cylinder is centred at the origin);
200 time steps, \(t \in [0, 19.9]\), with \(\Delta t = 0.1\).
This gives 1,000,000 space–time points in total.
import os, urllib.request
if not os.path.exists("cylinder_nektar_wake.mat"):
    urllib.request.urlretrieve("https://github.com/maziarraissi/PINNs/raw/master/main/Data/cylinder_nektar_wake.mat", "cylinder_nektar_wake.mat")
Defining the Problem#
Question 02: Cylinder-Induced Wake#
Flow past a cylinder is a classic fluid-mechanics problem, in no small part because of the insight it provides into wakes. What is a wake in fluid dynamics, and why is it important to study? What is a von Kármán vortex street, and at what Reynolds numbers does it form? What examples of flow past a cylinder are there in engineering or physics? Can you think of examples from your day-to-day life?
[ Answer Here ]
Question 03: Training on Flow-Field Data#
Any machine-learning model worth its weights must be trained on an adequate amount of data. So, for training a surrogate model of a flow, where can the data come from? List at least three computational or experimental techniques that fluid-mechanics researchers use to generate flow-field data. For each, briefly note the issues with using it to produce training data.
[ Answer Here ]
A PINN for the Cylinder Wake#
PINNs have been shown to be effective when data are scarce, so let’s test them on the cylinder wake. The goals are to reconstruct the flow from a limited number of velocity measurements, to infer the pressure field without ever training on pressure data, to quantify the uncertainty, and to analyze how much the embedded physics can compensate for a lack of training data. We briefly discuss the relevant physics and equations, and propose hyperparameters for the PINN.
Note: the training data and the following work draw heavily on the original PINN paper [1], Section 4.1.1. There will be some differences in implementation. You are encouraged to consult the paper, but do not copy its code or text.
Quick Primer on the Relevant Physics#
All flows must satisfy the conservation of momentum and the conservation of mass. For a 2D incompressible flow, the momentum equations (Navier–Stokes) are
where \(u\) and \(v\) are the \(x\) and \(y\) components of the velocity, \(p\) is the pressure (divided by the constant density), and \(\nu\) is the kinematic viscosity. Subscripts denote partial derivatives, e.g. \(u_x = \partial u/\partial x\). In the units of this dataset, \(\nu = 0.01\) (\(Re = 100\)).
Mass conservation for an incompressible flow requires \(u_x + v_y = 0\). This is satisfied automatically if the velocity is derived from a streamfunction \(\psi\):
So the network predicts \(\psi\) and \(p\), and the velocity is obtained by differentiating \(\psi\). The pressure appears only through its gradient, so it is determined only up to an additive constant.
Recommended PINN Hyperparameters#
Item |
Recommendation |
|---|---|
Layers |
\([3] + 8 \times [20] + [2]\), with tanh activations |
Inputs |
\([x, y, t]\), rescaled to \([-1, 1]\) |
Outputs |
\([\psi(x, y, t),\ p(x, y, t)]\) |
Data loss |
MSE of \(u\) and \(v\) only. Do not include \(p\); the physics determines it. |
Physics loss |
\(\frac{1}{N}\sum_{i=1}^{N} \left(f(x^i, y^i, t^i)^2 + g(x^i, y^i, t^i)^2\right)\) |
PDE residuals |
\(\begin{aligned} f &= u_t + \lambda_1(uu_x + vu_y) + p_x - \lambda_2(u_{xx} + u_{yy}), \\ g &= v_t + \lambda_1(uv_x + vv_y) + p_y - \lambda_2(v_{xx} + v_{yy}) \end{aligned}\) |
Coefficients |
Forward problem: fix \(\lambda_1 = 1\), \(\lambda_2 = \nu = 0.01\). Inverse problem (optional, Question 10): learn them. |
Optimizer |
Adam (learning rate \(10^{-3}\)) for a warm-up, followed by L-BFGS ( |
Compute requirements#
PINNs for Navier–Stokes are expensive to train. Each step needs third-order derivatives of the network (\(\psi \to u \to u_{xx}\)) at every training point. With 4000 points, one Adam step takes roughly 0.15 s on a laptop CPU. Some guidance from test runs:
Adam alone converges slowly. It first learns only the mean flow and stays on that plateau for thousands of steps. After 3000 Adam steps (about 9 minutes on a CPU), the vortex shedding was still not captured: the relative error of \(v\) was about 100%.
A short Adam warm-up followed by L-BFGS works much better. 500 Adam steps, then 40 calls of
LBFGS.stepwithmax_iter=50, took about 8 minutes on a CPU. This reached relative errors of about 8% for \(u\), 26% for \(v\), and 50% for the pressure (which is never trained on) at \(t = 10\). Longer training keeps improving the result. Ref. [1] used 200,000 Adam iterations followed by L-BFGS.
Use a GPU (e.g. Google Colab) for your final runs if you can. Develop and debug with short runs, and save your trained models (torch.save) so that you do not have to retrain them.
Helper Code and Dataset Notes#
Helper code to load the data and to plot the flow field is provided at the bottom of this notebook. You may find it cleaner to do most of the coding in a separate notebook or Python script.
The dataset covers a region downstream of the cylinder. You do not need to impose boundary or initial conditions for this project: the data play that role.
Question 05: Activate It!#
Why does the choice of activation function matter when building a PINN for a second-order PDE? What would go wrong with ReLU?
[ Answer Here ]
Question 06: Balance It!#
How do you balance the data loss against the physics loss? Discuss the relative weight of the two terms, and the number and placement of the collocation points. Must the collocation points coincide with the data points?
[ Answer Here ]
Question 07: Make It!#
Build a PINN to reconstruct the flow field. Randomly select 4000 space–time points \((x, y, t)\) uniformly from the 1,000,000 in the dataset as training data, and use the remaining points for validation and testing. Use the training points as collocation points too, or add extra collocation points, and justify your choice.
Use the helper functions to plot the predicted and the true flow fields, including the pressure, at a few time steps.
Report the relative \(L_2\) error of \(u\), \(v\) and \(p\) on held-out points. For \(p\), first subtract the mean of each field, since the pressure is only determined up to a constant.
[ Answer Here ]
Question 08: Analyze It!#
For the PINN you built above, quantify both its accuracy and its uncertainty. This is open-ended, but address the following:
Estimate the uncertainty with Monte Carlo dropout [5]: add dropout layers and keep them active at prediction time, then use the spread of many stochastic predictions. Alternatively, train a small ensemble of PINNs with different random seeds. Note that dropout makes the network function noisy, which interacts with the derivatives in the physics loss. Comment on how this affects training.
For accuracy, compare the total, data and physics losses on the training and held-out points.
This is both a spatial and a temporal problem: show how the error and the uncertainty vary in space (maps at one time step) and in time (e.g. the spatially averaged error versus \(t\)). Where is the model least accurate, and why?
[ Answer Here ]
Question 09: Lower It!#
Train at least two more PINNs with progressively less training data (e.g. 2000, 1000, 500 points), and, for comparison, a plain neural network with the same architecture but no physics loss. How small can the training set become before the PINN’s error becomes unacceptably large? How does the plain network compare, in particular for the pressure, which it cannot learn at all without pressure data? Plot the error versus the number of training points for both.
[ Answer Here ]
Question 10: Inverse Problem (optional)#
Make \(\lambda_1\) and \(\lambda_2\) trainable parameters (initialized to 0), and train on the same 4000 points, as in Ref. [1]. Do you recover \(\lambda_1 = 1\) and \(\lambda_2 = 0.01\)? What happens if you add noise (e.g. 1%) to the training velocities?
[ Answer Here ]
References#
[1] M. Raissi, P. Perdikaris, G. E. Karniadakis, “Physics-informed neural networks: A deep learning framework for solving forward and inverse problems involving nonlinear partial differential equations,” J. Comput. Phys. 378, 686 (2019). doi:10.1016/j.jcp.2018.10.045. Code and data: maziarraissi/PINNs
[2] G. E. Karniadakis, I. G. Kevrekidis, L. Lu, P. Perdikaris, S. Wang, L. Yang, “Physics-informed machine learning,” Nat. Rev. Phys. 3, 422 (2021). doi:10.1038/s42254-021-00314-5
[3] S. Cuomo, V. S. Di Cola, F. Giampaolo, G. Rozza, M. Raissi, F. Piccialli, “Scientific Machine Learning Through Physics-Informed Neural Networks: Where we are and What’s Next,” J. Sci. Comput. 92, 88 (2022). doi:10.1007/s10915-022-01939-z
[4] C. D. Cantwell et al., “Nektar++: An open-source spectral/hp element framework,” Comput. Phys. Commun. 192, 205 (2015). doi:10.1016/j.cpc.2015.02.008
[5] Y. Gal, Z. Ghahramani, “Dropout as a Bayesian Approximation: Representing Model Uncertainty in Deep Learning,” Proc. ICML (2016). arXiv:1506.02142
Acknowledgements#
Initial version: Pranet Patil with feedback from Mark Neubauer
Revised: 2026 (PINN introduction added)
© Copyright 2026
Starter Code#
from scipy.io import loadmat
import numpy as np
import matplotlib.pyplot as plt
from matplotlib.animation import FuncAnimation
import torch
import os, urllib.request
def import_wake_data(path="cylinder_nektar_wake.mat"):
    """
    Imports the full dataset (nondimensional units, Re = 100).
    - 5000 spatial points on a 100 (x) x 50 (y) grid, x in [1, 8], y in [-2, 2]; x varies fastest
    - 200 times, t in [0, 19.9], dt = 0.1
    Returns dictionaries position = {x, y (N x 1), t (T x 1)} and flow = {u, v, p (N x T)}.
    """
    wake_data = loadmat(path)
    x = wake_data["X_star"][:, 0:1]   # N x 1
    y = wake_data["X_star"][:, 1:2]   # N x 1
    t = wake_data["t"]                # T x 1
    U_star = wake_data["U_star"]      # N x 2 x T
    position = {"x": x, "y": y, "t": t}
    flow = {"u": U_star[:, 0, :], "v": U_star[:, 1, :], "p": wake_data["p_star"]}
    print(f"# of Spatial Points (x, y): {x.shape[0]}")
    print(f"# of Temporal Points (t):   {t.shape[0]}")
    return position, flow
def generate_flow_field(model, t, resolution_factor=1, device="cpu"):
    """
    Uses your trained PINN to predict the flow on a regular grid at a single time t.

    TODO: adapt the marked section to your model's interface. Here we assume the model maps
    a tensor of shape (M, 3) with columns [x, y, t] to (M, 2) with columns [psi, p].

    Returns 1D numpy arrays x, y (flattened grid, x varying fastest), t, u, v, p,
    in the format expected by plot_wake_snapshot.
    """
    model.eval()
    xg = np.linspace(1, 8, 100 * resolution_factor)
    yg = np.linspace(-2, 2, 50 * resolution_factor)
    X, Y = np.meshgrid(xg, yg)                       # shape (ny, nx); flattening makes x vary fastest
    x, y = X.ravel(), Y.ravel()
    inputs = torch.tensor(np.column_stack([x, y, np.full_like(x, t)]), dtype=torch.float32,
                          device=device, requires_grad=True)

    # ---- adapt this section to your model ----
    out = model(inputs)
    psi, p = out[:, 0:1], out[:, 1:2]
    dpsi = torch.autograd.grad(psi, inputs, torch.ones_like(psi))[0]
    u, v = dpsi[:, 1], -dpsi[:, 0]                   # u = psi_y, v = -psi_x
    # ------------------------------------------

    return x, y, float(t), u.detach().cpu().numpy(), v.detach().cpu().numpy(), p.detach().cpu().numpy().ravel()
def plot_wake_snapshot(x, y, t, u, v, p):
    """
    Plots both the velocity and pressure field of the cylinder wake.
    Use this for the raw data or to see your model's output

    Feel free to copy and modify this code to visualize error or uncertainty plots.

    Inputs:
    x, y: 1D numpy arrays (N_spatial,)
    t: float representing current time
    u_star, v_star, p_star: 1D numpy arrays representing the flow variable for each point (N_spatial,)
    """

    N = x.shape[0]

    # 1. Determine grid dimensions for reshaping
    nx = len(np.unique(x))
    ny = len(np.unique(y))

    # Reshape vectors into 2D grids (NY x NX)
    X = x.reshape(ny, nx)
    Y = y.reshape(ny, nx)
    U = u.reshape(ny, nx)
    V = v.reshape(ny, nx)
    P = p.reshape(ny, nx)


    current_time = t

    fig, ax = plt.subplots(2, 1, figsize=(12, 8), sharex=True)


    # --- Subplot 1: Velocity Magnitude + Quiver ---
    vel_mag = np.sqrt(U**2 + V**2)
    im1 = ax[0].imshow(vel_mag, extent=[x.min(), x.max(), y.min(), y.max()],
                       origin='lower', cmap='viridis', aspect='equal')

    # Quiver
    skip = (slice(None, None, max(1, ny // 12)), slice(None, None, max(1, nx // 25)))   # about 12 x 25 arrows
    ax[0].quiver(X[skip], Y[skip], U[skip], V[skip],
                 color='white', alpha=0.3, scale=None)
    ax[0].set_ylabel("y")


    # --- Subplot 2: Pressure Field ---
    im2 = ax[1].imshow(P, extent=[x.min(), x.max(), y.min(), y.max()],
                       origin='lower', cmap='RdBu_r', aspect='equal')


    fig.suptitle(f"Cylinder Wake Flow Visualization at t = {current_time:.3f}", fontsize=16, x = 0.625)
    ax[0].set_title("Velocity Field")
    ax[1].set_title("Pressure Field")
    fig.colorbar(im1, ax=ax[0], label="|U|")
    fig.colorbar(im2, ax=ax[1], label="p")
    ax[1].set_xlabel("x")
    ax[1].set_ylabel("y")

    plt.tight_layout(rect=[0, 0.03, 1, 0.95])
    plt.show()
def animate_wake(x, y, t, u_star, v_star, p_star, dt = 0.1):
    """
    Creates an animation of the cylinder wake flow. It's fun stuff
    (Use this to visualize the flow field, but due to file size contraints don't worry about attaching all of them to the submission)

    Inputs:
    x, y: 1D numpy arrays (N_spatial,)
    t: 1D numpy array (T_steps,)
    u_star, v_star, p_star: 2D numpy arrays (N_spatial, T_steps)
    """


    N = x.shape[0]
    nx = len(np.unique(x))
    ny = len(np.unique(y))
    X_grid = x.reshape(ny, nx)
    Y_grid = y.reshape(ny, nx)

    fig, ax = plt.subplots(2, 1, figsize=(12, 8), sharex=True)

    # Calculate global min/max for consistent color scales
    v_min, v_max = 0, np.sqrt(u_star**2 + v_star**2).max()
    p_min, p_max = p_star.min(), p_star.max()


    # Initial plot for Velocity
    def get_vel_mag(idx):
        return np.sqrt(u_star[:, idx]**2 + v_star[:, idx]**2).reshape(ny, nx)

    im_v = ax[0].imshow(get_vel_mag(0), extent=[x.min(), x.max(), y.min(), y.max()],
                        origin='lower', cmap='viridis', aspect='equal', vmin=v_min, vmax=v_max)

    # Quiver
    skip = (slice(None, None, max(1, ny // 12)), slice(None, None, max(1, nx // 25)))
    u_init = u_star[:, 0].reshape(ny, nx)[skip]
    v_init = v_star[:, 0].reshape(ny, nx)[skip]
    q = ax[0].quiver(X_grid[skip], Y_grid[skip], u_init, v_init,
                     color='white', alpha=0.3)


    # Initial plot for Pressure
    im_p = ax[1].imshow(p_star[:, 0].reshape(ny, nx), extent=[x.min(), x.max(), y.min(), y.max()],
                        origin='lower', cmap='RdBu_r', aspect='equal', vmin=p_min, vmax=p_max)

    # Formatting
    ax[0].set_title("Velocity Field")
    ax[1].set_title("Pressure Field")
    fig.colorbar(im_v, ax=ax[0])
    fig.colorbar(im_p, ax=ax[1])
    time_text = ax[0].text(0.02, 0.9, '', transform=ax[0].transAxes, color='white', fontweight='bold')


    # Update Function for Animation
    # TODO: Update as needed if you repurpose this code
    def update(frame):
        # Extract the N spatial points for the current time frame
        # u[:, frame] extracts the column, resulting in size (N,)
        u_f = u_star[:, frame].reshape(ny, nx)
        v_f = v_star[:, frame].reshape(ny, nx)
        p_f = p_star[:, frame].reshape(ny, nx)

        # Update the artists
        im_v.set_array(np.sqrt(u_f**2 + v_f**2))
        q.set_UVC(u_f[skip], v_f[skip])
        im_p.set_array(p_f)

        time_text.set_text(f"t = {t[frame, 0]:.3f}")
        return [im_v, q, im_p, time_text]


    ani = FuncAnimation(fig, update, frames=len(t), interval=50, blit=True)
    plt.tight_layout()
    ani.save('wake_animation.gif', writer='pillow', fps=10)
    return ani
Example: plot the true flow field at one time step.
position, flow = import_wake_data()
k = 100   # time index
plot_wake_snapshot(position["x"].ravel(), position["y"].ravel(), position["t"][k, 0],
                   flow["u"][:, k], flow["v"][:, k], flow["p"][:, k])